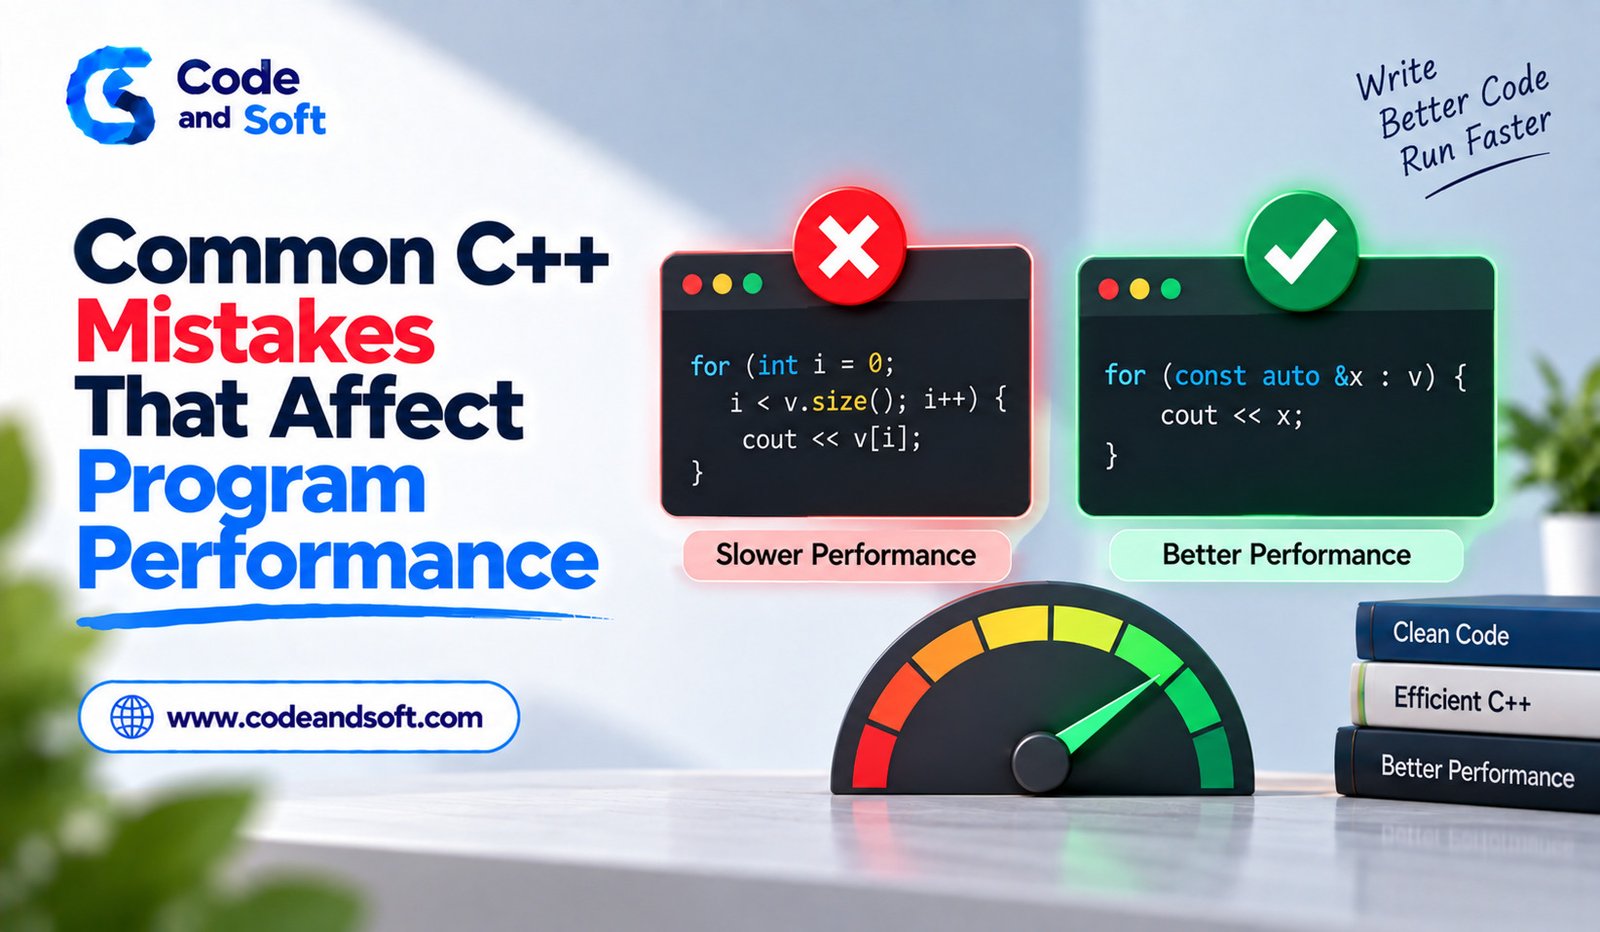
C++ is widely known for giving developers strong control over memory, hardware resources and program execution. That control makes the language suitable for demanding applications such as game engines, operating systems, financial software, embedded systems and high-performance tools. However, C++ does not automatically guarantee that every program will run efficiently.
Small programming decisions can have a noticeable effect on performance, especially when they occur inside frequently executed code. A program may produce the correct output but still consume excessive memory, perform unnecessary calculations or spend too much time moving data.
For new C++ programmers, understanding common performance mistakes is an important step toward writing faster and more reliable applications. The following are some of the mistakes developers should watch for when building C++ programs.
Creating Unnecessary Copies of Data
One of the most common performance problems in C++ is copying objects unnecessarily.
Consider a function that receives a large vector by value:
void processData(std::vector<int> numbers)
{
// Process numbers
}
When the function is called, a copy of the vector may be created. If the vector contains thousands or millions of elements, that copy can require significant time and memory.
When the function only needs to read the data, a constant reference is often more appropriate:
void processData(const std::vector<int>& numbers)
{
// Read numbers
}
The function can access the original collection without creating another copy.
Understanding when objects are copied and when references can be used is one of the most useful performance skills for C++ developers.
Ignoring Move Semantics
Modern C++ provides move semantics to reduce unnecessary copying of resources.
A beginner may return or transfer large objects without understanding how those objects are moved or copied. In situations involving temporary objects or ownership transfer, move operations can avoid expensive duplication of resources.
Move semantics become particularly important when working with objects containing dynamically allocated memory, large strings or other resource-heavy data.
Developers do not need to manually use std::move everywhere. In fact, unnecessary use of std::move can make code harder to understand. The better approach is to learn how move constructors, move assignment and temporary objects work before applying move semantics.
Choosing the Wrong Data Structure
The choice of data structure can strongly influence program performance.
For example, using a vector for every situation may seem convenient, but it is not always the best choice. A program that frequently searches for unique values might benefit from a set or unordered set. A key-value lookup problem may be better suited to a map or unordered map.
Similarly, inserting or removing elements repeatedly from the middle of a vector can involve shifting other elements.
The right data structure depends on how the program uses its data. Developers should consider operations such as searching, inserting, deleting and accessing elements before selecting a container.
Reserving Too Little Space in Vectors
A vector can automatically grow when more elements are added. While this makes vectors convenient, repeated growth can sometimes result in additional memory allocations and element movement.
For example:
std::vector<int> numbers;
for (int i = 0; i < 100000; ++i)
{
numbers.push_back(i);
}
If the approximate number of elements is already known, the program can reserve space in advance:
std::vector<int> numbers;
numbers.reserve(100000);
The reserve() function does not change the number of elements. Instead, it prepares enough capacity for future additions.
This can reduce repeated reallocations when building large collections.
Performing Expensive Work Inside Loops
Loops often become performance-sensitive areas because the code inside them may execute thousands or millions of times.
A common mistake is performing the same calculation repeatedly when its result could be calculated once.
For example, if a value does not change during a loop, calculating it again on every iteration is unnecessary.
Developers should examine frequently executed loops and ask whether calculations, function calls or object creation can be moved outside the loop.
This does not mean every loop needs aggressive optimization. The goal is to identify work that genuinely does not need to be repeated.
Using Inefficient String Operations
Strings are another area where unnecessary work can affect performance.
Repeatedly creating, copying and modifying large strings can increase memory usage and processing time.
For example, constructing a new string repeatedly inside a large loop may create unnecessary temporary objects.
Developers should understand how strings are stored and modified and avoid creating objects repeatedly when a more efficient approach is available.
For larger text-processing applications, techniques such as reserving string capacity and using appropriate string operations can make a difference.
Ignoring Memory Allocation Costs
Dynamic memory allocation is useful, but frequent allocations can become expensive.
A program that continuously creates and destroys small objects may spend a significant amount of time managing memory rather than performing useful work.
This can happen in loops, frequently called functions or systems that create many short-lived objects.
Developers should avoid optimizing memory allocation blindly, but they should recognize allocation-heavy sections when profiling shows that memory management is contributing to slow execution.
Appropriate containers, object reuse and better data organization can sometimes reduce unnecessary allocations.
Using Virtual Functions Without Understanding the Cost
Object-oriented programming is an important part of C++, and virtual functions provide useful runtime polymorphism.
However, developers should understand that dynamic dispatch can introduce some overhead compared with direct function calls.
This overhead is usually small and should not be treated as a reason to avoid virtual functions. Problems can arise when developers assume that every abstraction has zero runtime cost in highly performance-sensitive code.
Good C++ programming involves balancing clean design with actual performance requirements.
Creating Objects Unnecessarily
Another common mistake is repeatedly constructing objects when an existing object could be reused.
For example, creating temporary containers or large helper objects inside a frequently executed loop can result in repeated construction, allocation and destruction.
Moving object creation outside the loop or reusing resources may reduce this overhead.
However, object reuse should not make the code complicated unnecessarily. Clear and maintainable code remains important.
Passing Small Objects Incorrectly
References are useful for avoiding copies, but using them blindly is not always better.
Very small types such as integers, characters and simple lightweight values can often be passed directly.
For example:
void calculate(int value)
{
// Work with value
}
Using a reference for every parameter does not automatically make a function faster.
Developers should understand the size and behavior of the object before deciding whether to pass by value, reference or constant reference.
Ignoring Compiler Optimization
Modern C++ compilers can perform many optimizations automatically, but developers still need to build code in appropriate configurations.
A program compiled without optimization can behave very differently from a properly optimized release build.
For performance testing, developers should use suitable compiler optimization settings and compare results using realistic workloads.
At the same time, compiler optimization should not be used as an excuse for inefficient program design. A compiler cannot always eliminate unnecessary algorithms, poor data structures or excessive memory operations.
Optimizing Without Measuring
Perhaps the biggest performance mistake is optimizing based on assumptions.
A developer may spend hours changing code that looks slow while ignoring the actual performance bottleneck.
Profiling tools can help identify where a program spends its execution time. Measurements can reveal whether the real problem is CPU processing, memory access, allocation, input/output or another component.
A useful performance workflow is simple: measure the application, identify the bottleneck, make a focused change and measure again.
This approach is generally more reliable than guessing.
Writing Code That Is Too Complex to Optimize
Performance improvements should not make programs unnecessarily difficult to understand.
Sometimes developers introduce complicated techniques because they assume they must produce the fastest possible code. The result can be difficult to maintain while providing little real-world improvement.
A better approach is to start with clean and sensible code, measure its performance and optimize the sections that actually matter.
Readable code also makes future performance work easier because developers can understand the behavior of the application more quickly.
How Beginners Can Improve C++ Performance
New C++ programmers should focus on understanding the fundamentals before learning advanced optimization techniques.
Learn how copying works, how references behave, how dynamic memory is managed and how STL containers operate. Become familiar with algorithms and their general performance characteristics.
It is also useful to practice with programs that process larger amounts of data. A small application may hide performance problems that become obvious when the workload increases.
Most importantly, develop the habit of measuring performance instead of relying only on intuition.
Final Thoughts
C++ provides powerful tools for creating high-performance software, but developers must use those tools thoughtfully. Unnecessary copies, inefficient data structures, excessive memory allocation, repeated calculations and poorly designed loops can all affect program performance.
The solution is not to optimize every line of code. Good performance comes from choosing appropriate data structures, avoiding unnecessary work and understanding how the program uses memory and processing resources.
For beginners, the best approach is to write clear C++ code first, measure its behavior and then improve the areas that genuinely limit performance. With practice, these habits can help developers build C++ applications that are not only correct but also efficient, scalable and easier to maintain.