
Statistical analysis can feel difficult when you have a large amount of data to work with. Finding patterns, comparing numbers, creating charts, testing ideas, and understanding results can take a lot of time when everything has to be done manually. This is where R becomes useful.
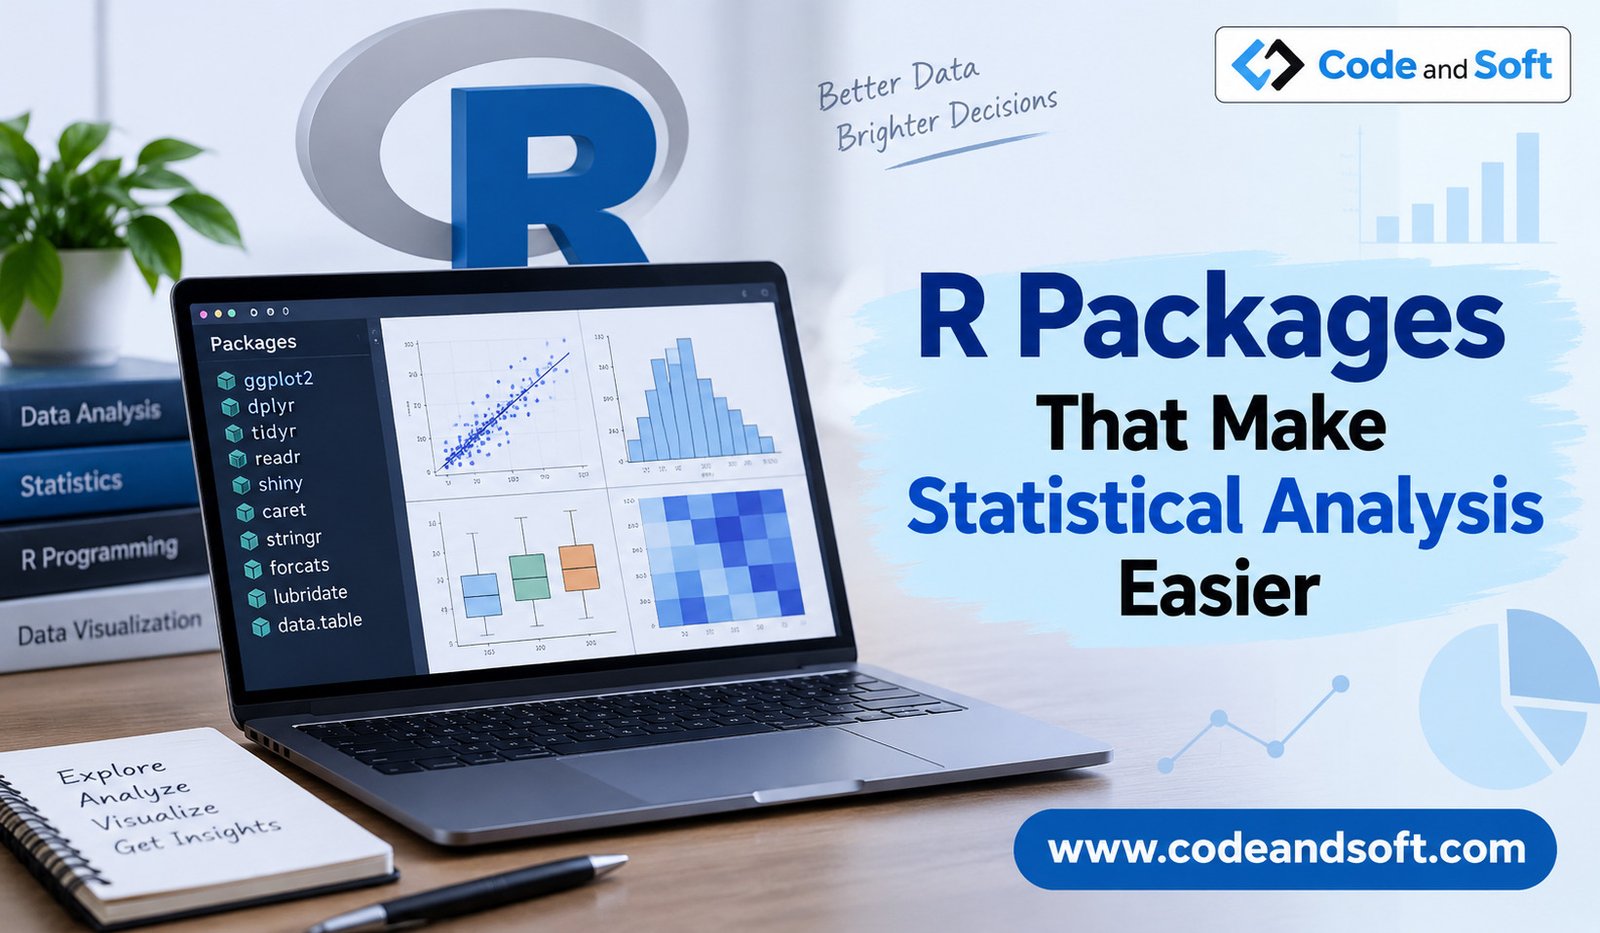
R is a popular programming language designed for working with data and statistics. One of its biggest advantages is the large number of packages available for different types of work. An R package is simply a collection of tools and functions that helps you perform specific tasks without having to create everything yourself.
The right packages can make statistical analysis faster, clearer, and easier to understand. Whether you are a student learning statistics, a researcher working with survey data, or a developer building data-based applications, R packages can reduce the amount of repetitive work involved.
In this article, we will look at some of the most useful R packages that can make statistical analysis easier and explain what each one does in simple terms.
Why R Packages Are Useful for Statistical Analysis
R already includes many tools for statistics, but packages give it much more power. Instead of writing long pieces of code for common tasks, you can use functions that have already been created and tested by other developers and researchers.
For example, imagine that you have a spreadsheet containing thousands of customer records. You may want to remove empty values, calculate averages, compare groups, or create a chart showing changes over time. Doing these tasks one by one can be tiring.
Packages such as dplyr, ggplot2, tidyr, and readr provide convenient ways to handle these common jobs. They allow you to focus more on understanding your data instead of spending most of your time preparing it.
Another important benefit is that many R packages use readable commands. Once you understand the basic idea behind them, you can often understand what a piece of code is trying to do simply by looking at it.
dplyr for Working With Data
When statistical analysis begins, one of the first challenges is usually getting the data into a useful form. You may need to select certain columns, filter rows, create new values, or calculate totals.
The dplyr package is one of the most popular choices for this type of work.
Suppose you have sales information containing product names, prices, dates, and sales amounts. With dplyr, you can quickly select the information you need and calculate useful results.
For example, you can find the average sales amount for each product or select records from a particular month. You can also create new columns based on existing information.
The main advantage of dplyr is that its commands are relatively easy to read. This makes it useful for beginners as well as people who regularly work with data.
Instead of manually changing a large table, you can tell R what you want and let the package handle the work.
ggplot2 for Creating Clear Charts
Numbers are often easier to understand when they are shown visually. A good chart can reveal a pattern that may be difficult to notice in a table.
The ggplot2 package is one of the best-known R packages for creating charts. It can be used to create bar charts, line charts, scatter plots, histograms, and many other types of visual displays.
For example, if you have monthly website traffic data, a line chart can show whether visits are increasing or decreasing. If you are comparing sales between several products, a bar chart can make the differences easier to see.
One of the useful features of ggplot2 is that you can build a chart gradually. You start with your data and then tell R which information should appear on the horizontal and vertical parts of the chart. You can then adjust labels, titles, sizes, and other visual details.
This makes ggplot2 particularly useful when statistical results need to be presented to other people.
tidyr for Organizing Untidy Data
Real-world data is rarely perfect when you first receive it. Information may be placed in the wrong columns, repeated in an inconvenient format, or stored in a way that makes analysis difficult.
The tidyr package helps organize this type of data.
For example, you might receive a table where different months are stored as separate columns. For some types of analysis, it is easier to have one column for the month and another for the value. tidyr provides functions that help you change the structure of a table into a more useful format.
This process may sound complicated, but the basic idea is simple: tidyr helps you arrange your data so that R can work with it more easily.
Good data organization is important because even the best statistical method can produce confusing results if the original data is arranged incorrectly.
readr for Importing Data
Before you can analyze data, you need to bring it into R. The readr package makes this process easier, especially when working with common text-based files such as CSV files.
CSV files are widely used because they can be created by spreadsheet programs and many other software tools. A CSV file may contain thousands or even millions of rows, making manual copying impractical.
With readr, you can import these files into R with simple commands. The package also helps R understand the type of information stored in different columns.
For example, it can recognize dates, numbers, and text. This saves time and reduces some common problems that can occur when data is imported incorrectly.
For anyone who regularly receives data from spreadsheets or other systems, readr can become a very useful part of the R workflow.
lubridate for Working With Dates
Dates can cause surprising problems during statistical analysis. A date may appear as text in one file, as a number in another, or in different formats across different sources.
The lubridate package makes working with dates much easier.
It can help you extract the year, month, or day from a date. It can also help calculate the amount of time between two dates.
Imagine that you are studying customer activity and want to know how long customers remain active after signing up. You need to compare signup dates with later activity dates. lubridate can make this type of calculation much simpler.
The package is especially helpful for research involving sales, website visits, financial records, surveys, or any other information that changes over time.
janitor for Cleaning Data
Data cleaning is often one of the least exciting parts of statistical analysis, but it is extremely important. Messy column names, duplicate records, empty values, and inconsistent information can create problems later.
The janitor package provides simple tools for cleaning tables.
For example, a spreadsheet might contain column names with spaces, capital letters, or unusual symbols. janitor can help turn those names into a cleaner and more consistent format.
It can also help identify duplicate records and create simple summary tables.
This makes janitor useful when your data comes from spreadsheets or other sources where the information has been entered manually.
Instead of spending a long time fixing small problems yourself, you can use the package to handle many common cleaning tasks.
readxl for Excel Files
Many businesses, schools, and researchers store their information in Microsoft Excel files. The readxl package allows R users to bring Excel data directly into their analysis.
This is useful because you do not always have to convert an Excel file into another format before working with it.
For example, suppose a company maintains monthly sales information in an Excel workbook. You can use readxl to import the required sheet into R and then use other packages to clean, analyze, and visualize the information.
It supports common Excel file formats and is relatively straightforward to use.
For beginners who already work with Excel, readxl can provide a comfortable connection between spreadsheets and R.
broom for Making Statistical Results Easier to Read
Statistical tests often produce results that contain several pieces of information. These results can be difficult to work with when they are presented in their original R format.
The broom package helps turn many statistical results into clean tables.
For example, after running a statistical model, you may want to see the estimated values, their uncertainty, and other important information in a simple table. broom can organize these results into a format that is easier to read and use.
This is particularly helpful when you need to include statistical results in a report or combine results from several analyses.
The package does not replace the statistical method itself. Instead, it makes the results easier to handle after the analysis has been completed.
dplyr and ggplot2 Work Well Together
One reason the R ecosystem is so useful is that packages can work together.
You might use readr to import a CSV file, tidyr to organize it, dplyr to filter and summarize the information, and ggplot2 to create a chart.
For example, imagine you are analyzing five years of sales records. You can first import the data, clean the dates, remove incorrect records, calculate yearly sales, and then create a chart showing the changes over time.
Each package handles a different part of the process, but they can be used together in the same project.
This approach makes large analysis tasks feel more manageable because you can break the work into smaller steps.
caret for Easier Predictive Analysis
When your analysis moves beyond basic summaries and comparisons, you may want to use past data to make predictions. The caret package provides tools that can help with this type of work.
For example, a business might want to predict whether a customer is likely to purchase a product. A researcher might want to estimate an outcome based on several pieces of information.
caret helps with tasks such as preparing data, creating prediction models, and checking how well those models perform.
Predictive analysis can become complicated, so beginners should start with basic statistics before moving into this area. However, caret can be useful once you are comfortable working with data and want to explore prediction.
shiny for Interactive Statistical Results
Sometimes a static report or chart is not enough. You may want people to change values and immediately see how the results change.
The shiny package allows R users to create interactive web applications.
For example, you could create a simple application where users choose a year, product, or region and then see the relevant statistics and charts. This can make statistical information much easier for non-technical users to explore.
Shiny is especially useful for researchers, analysts, teachers, and businesses that need to share data results with others.
You do not need to build a complete website from scratch. R and Shiny can handle much of the work.
How to Choose the Right R Packages
You do not need to install dozens of packages just because they are popular. The best approach is to choose packages based on the work you actually need to complete.
If your main problem is organizing tables, dplyr and tidyr are good starting points. If you need charts, ggplot2 is a strong choice. For importing files, readr and readxl can save time. For cleaning messy spreadsheets, janitor can be useful.
It is also helpful to learn a small number of packages properly instead of trying to learn everything at once. Once you understand the basics, you can add more packages as your projects become more advanced.
Making Statistical Analysis Less Difficult
R can seem intimidating when you first see large amounts of code. However, packages make the learning process much easier because you do not have to build every function yourself.
The most important thing is to understand what you are trying to find in your data. Once that is clear, you can choose a package that helps you perform the required task.
Packages such as dplyr, ggplot2, tidyr, readr, readxl, lubridate, and janitor cover many of the everyday tasks involved in statistical analysis. Other packages, such as broom, caret, and shiny, become useful when you need to organize results, make predictions, or create interactive tools.
The biggest advantage of using these packages is not simply that they reduce the amount of code you write. They also make your work easier to repeat, check, and explain.
Conclusion
Statistical analysis does not have to mean spending hours performing the same data tasks manually. R packages can make many parts of the process faster and easier while allowing you to focus on the meaning behind your results.
For beginners, starting with a few practical packages is usually enough. dplyr can help you work with tables, ggplot2 can turn numbers into clear charts, tidyr can organize data, readr and readxl can bring information into R, and janitor can help clean it.
As your skills grow, packages such as lubridate, broom, caret, and shiny can help you handle more advanced projects.
The key is to learn gradually and use packages when they solve a real problem. With the right tools and regular practice, R can become a much simpler and more useful way to perform statistical analysis.